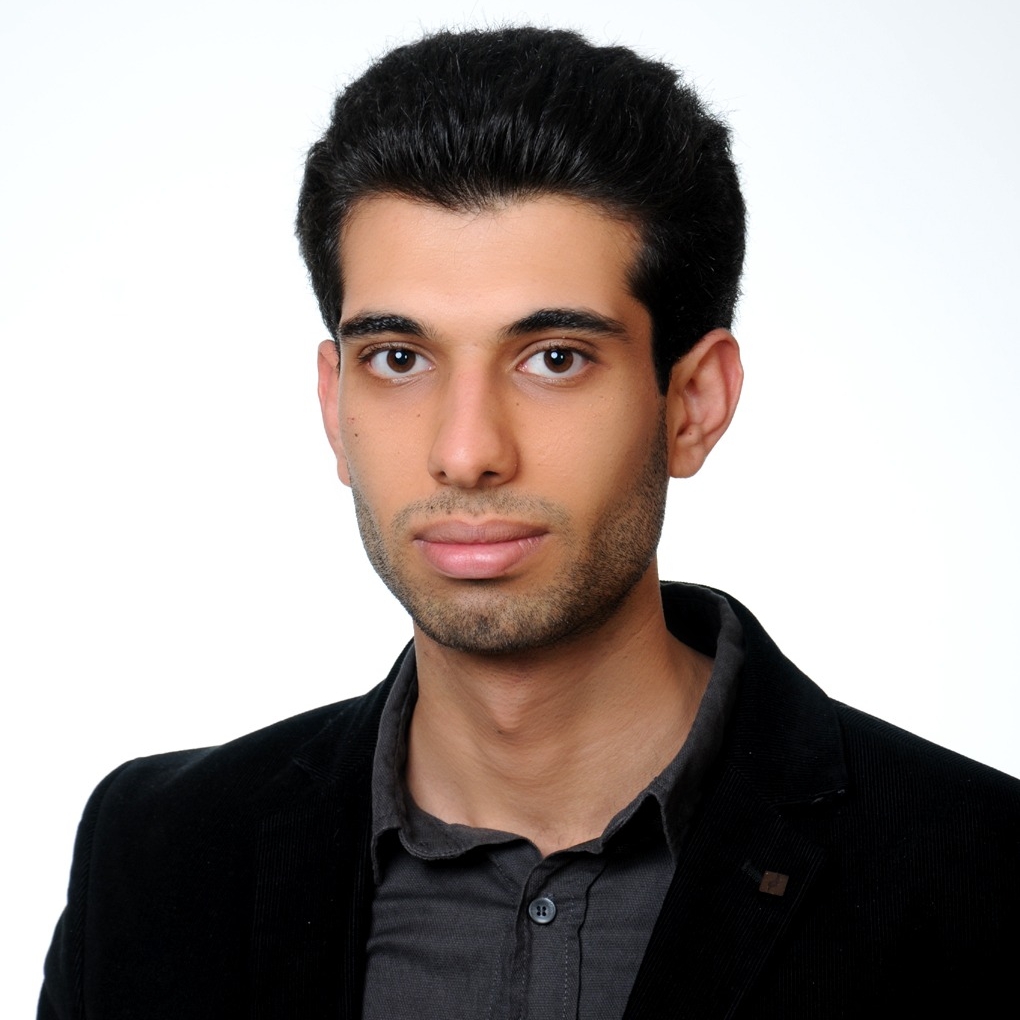
I am a doctoral researcher at INDElab, University of Amsterdam, advised by Dr. Victoria Degeler and Prof. Dr. Paul Groth.
My research focuses on interpretable decision-making through Neurosymbolic knowledge discovery and inference, applied to Digital Twins and tabular datasets.
I hold an MSc in Computer Science from TU Munich and a BSc in Computer Engineering from Yildiz
Technical University, Istanbul 
 .
Previously, I worked as a research assistant, software engineer and consultant.
I am open to collaborations — feel free to reach out: e.karabulut@uva.nl
Recent Activities
See all- October 2026 - Instead of asking "count how often these features co-occur together", our paper that asks "what does a learned model believe about their conditional dependency?" now got accepted at TMLR! Read more about how we re-frame rule learning for interpretable descriptive and predictive models in our paper!
- September 2026 - Together with Zeyu Zhang, we got the second place in ECML-PKDD 2026: GreenDIGIT Challenge on Predictive Modelling for Sustainable Digital Research Infrastructures.
- June 2026 - I will give a talk on Scalable Knowledge Discovery during the WAI Seminar @ VU.
- March 2026 - I will be visiting the Learning and Reasoning research group at Vrije Universiteit Amsterdam to collaborate on neurosymbolic knowledge discovery and interpretable machine learning models.
- February 2026 - A new pre-print describing a model-agnostic association rule learning framework is out! Tabular foundation models, when used as a conditional probability estimators, can instantiate the framework to learn association rules out-of-the-box, without training or frequent itemset mining.
Publications
See all-
E. Karabulut, D. Daza, P. Groth, M. C. Schut and V. Degeler. “Model-Agnostic Association Rule Learning with Tabular Foundation Models.”. Transactions on Machine Learning Research, 2026, openreview.net/forum?id=Y70lnNnA6T. Abstract PDF
Association Rule Mining (ARM) is a fundamental data mining technique for knowledge discovery in tabular data and is widely used in high-stakes decision-making. Existing approaches suffer from two limitations: reliance on frequent itemset mining leading to rule explosion in classical methods, and failure in low-data regimes in recent neural approaches. We reframe ARM as a conditional probability estimation problem and introduce a model-agnostic rule learning framework that extracts association rules from any conditional probabilistic model, decoupling rule extraction from frequent itemset mining. We introduce TabProbe, a probing-based algorithm that instantiates this framework, and demonstrate its generality across multiple model classes ranging from tree-based models to large pretrained foundation models. As a particularly powerful instantiation, we leverage tabular foundation models (TFMs), large models pretrained on diverse tabular data with strong in-context generalization, which can be applied out-of-the-box without task-specific training. Evaluation on 10 datasets of varying sizes shows that all framework instantiations achieve full data coverage with substantially fewer rules than state-of-the-art rule miners, and the best-performing instantiations achieve up to 15% higher association strength. Furthermore, TFM-learned rules have better predictive performance on unseen data and remain robust in low-data settings. Source code is available at https://github.com/DiTEC-project/tabprobe.
-
E. Karabulut, D. Daza, P. Groth and V. Degeler. "Discovering Association Rules in High-Dimensional Small Tabular Data". In ANSyA'25: 1st International Workshop on Advanced Neuro-Symbolic Applications, co-located with 28th European Conference on Artificial Intelligence (ECAI 2025). Abstract PDF
Association Rule Mining (ARM) aims to discover patterns between features in datasets in the form of propositional rules, supporting both knowledge discovery and interpretable machine learning in high-stakes decision-making. However, in high-dimensional settings, rule explosion and computational overhead render popular algorithmic approaches impractical without effective search space reduction, challenges that propagate to downstream tasks. Neurosymbolic methods, such as Aerial+, have recently been proposed to address the rule explosion in ARM. While they tackle the high dimensionality of the data, they also inherit limitations of neural networks, particularly reduced performance in low-data regimes. This paper makes three key contributions to association rule discovery in high-dimensional tabular data. First, we empirically show that Aerial+ scales one to two orders of magnitude better than state-of-the-art algorithmic and neurosymbolic baselines across five real-world datasets. Second, we introduce the novel problem of ARM in high-dimensional, low-data settings, such as gene expression data from the biomedicine domain with around 18k features and 50 samples. Third, we propose two fine-tuning approaches to Aerial+ using tabular foundation models. Our proposed approaches are shown to significantly improve rule quality on five real-world datasets, demonstrating their effectiveness in low-data, high-dimensional scenarios.
-
E. Karabulut, P. Groth, and V. Degeler. "Pyaerial: Scalable association rule mining from tabular data". SoftwareX, 31:102341, 2025. ISSN 2352-7110. Abstract PDF
Association Rule Mining (ARM) is a knowledge discovery technique that identifies frequent patterns as logical implications within transaction datasets and has been applied across domains such as e-commerce, healthcare, and cyber–physical systems. However, many state-of-the-art ARM methods, typically algorithmic or nature-inspired, suffer from rule explosion and long execution times. Aerial is a novel neurosymbolic ARM algorithm for tabular datasets that mitigates rule explosion using neural networks, while remaining compatible with existing approaches. Aerial transforms tables into transactions, uses an autoencoder to learn compact neural representations, and extracts logical rules from the neural representations. This paper presents PyAerial, a Python library that makes Aerial accessible and easy to use on generic tabular datasets for end users in a domain-independent way. Besides association rules, PyAerial can also be used to extract frequent itemsets, learn classification rules, apply item constraints to learn rules over the features of interest rather than all features, pre-discretize numerical data for ARM, and can be run on a GPU.
-
E. Karabulut, P. Groth, V. Degeler, Neurosymbolic association rule mining from tabular data, in: Proceedings of The 19th International Conference on Neurosymbolic Learning and Reasoning, volume 284 of Proceedings of Machine Learning Research, PMLR, 2025, pp. 565–588. Abstract PDF
Association Rule Mining (ARM) is the task of mining patterns among data features in the form of logical rules, with applications across a myriad of domains. However, high-dimensional datasets often result in an excessive number of rules, increasing execution time and negatively impacting downstream task performance. Managing this rule explosion remains a central challenge in ARM research. To address this, we introduce Aerial+, a novel neurosymbolic ARM method. Aerial+ leverages an under-complete autoencoder to create a neural representation of the data, capturing associations between features. It extracts rules from this neural representation by exploiting the model's reconstruction mechanism. Extensive evaluations on five datasets against seven baselines demonstrate that Aerial+ achieves state-of-the-art results by learning more concise, high-quality rule sets with full data coverage. When integrated into rule-based interpretable machine learning models, Aerial+ significantly reduces execution time while maintaining or improving accuracy.
-
Erkan Karabulut, Paul Groth, and Victoria Degeler. "Learning Semantic Association Rules from Internet of Things Data". Neurosymbolic Artificial Intelligence, 2025:1. doi:10.1177/29498732251377518. Abstract PDF
Association rule mining (ARM) is the task of discovering commonalities in data in the form of logical implications. ARM is used in the Internet of Things (IoT) for different tasks, including monitoring and decision-making. However, existing methods give limited consideration to IoT-specific requirements such as heterogeneity and volume. Furthermore, they do not utilize important static domain-specific description data about IoT systems, which is increasingly represented as knowledge graphs. In this paper, we propose a novel ARM pipeline for IoT data that utilizes both dynamic sensor data and static IoT system metadata. Furthermore, we propose an autoencoder-based neurosymbolic ARM method (Aerial) as part of the pipeline to address the high volume of IoT data and reduce the total number of rules that are resource-intensive to process. Aerial learns a neural representation of a given dataset and extracts association rules from this representation by exploiting the reconstruction (decoding) mechanism of an autoencoder. Extensive evaluations on three IoT datasets from two domains show that ARM on both static and dynamic IoT data results in more generically applicable rules while Aerial can learn a more concise set of high-quality association rules than the state-of-the-art, with full coverage over the datasets.
Recent Posts
See all- UvA Data Science Center Seminar: Scalable Knowledge Discovery — 11.11.2025
- NeSy2025 Conference Trip Report — 15.09.2025
- Scalable Neurosymbolic Tabular Rule Learning with Aerial+ — 30.07.2025